Placing ErrorBoundary
In this post, I want to talk about where you catch the errors you receive. In Error propagation I threw the same error from seven places and counted where each one landed. This post is about putting a catcher at each of those destinations.
Once you know the propagation paths, the next question follows on its own. How many ErrorBoundary should you have, and where do they go? Whether one is enough, whether every screen needs one, and whether the library's version overlaps with the one you wrote yourself, all get decided here.
Let me state the conclusion first. The number of ErrorBoundary is not a matter of taste; two things decide it. What throws, and what has to remain on screen when that thing dies. The first was covered in part 1, so this post starts with the second.
The blast radius you can afford
When people ask where to put an ErrorBoundary, they usually think about which component to wrap. That question has no answer. There are always several components you could wrap, and the code runs no matter which one you pick.
Ask it differently. If this dies, what has to remain on screen?
The answer differs from place to place. If the data that forms the backbone of a screen is missing, that screen does not hold together. An action button sitting alone, with no name and no status beside it, means nothing. Conversely, if one peripheral list fails and you blank out the whole screen, the user loses everything else they could have seen perfectly well. Actions that are hard to undo are different again. The user has to learn about the failure right where they clicked.
What an ErrorBoundary does is not catch a failure. It decides the area the fallback gets drawn over. The fallback is what you draw instead of the original screen when something fails. Everything you wrapped disappears. So the position of an ErrorBoundary is decided not by what you want to catch, but by the blast radius you can afford.
That radius splits into four levels.
| Layer | What it receives | How you undo it |
|---|---|---|
| Route | what the loader threw, whatever nothing below caught | revalidate() |
| Screen | what was thrown during render | resetErrorBoundary() |
| Region | what was thrown inside it | resetErrorBoundary() |
| Inside the component | a failed useQuery, a failed mutation |
refetch(), a toast |
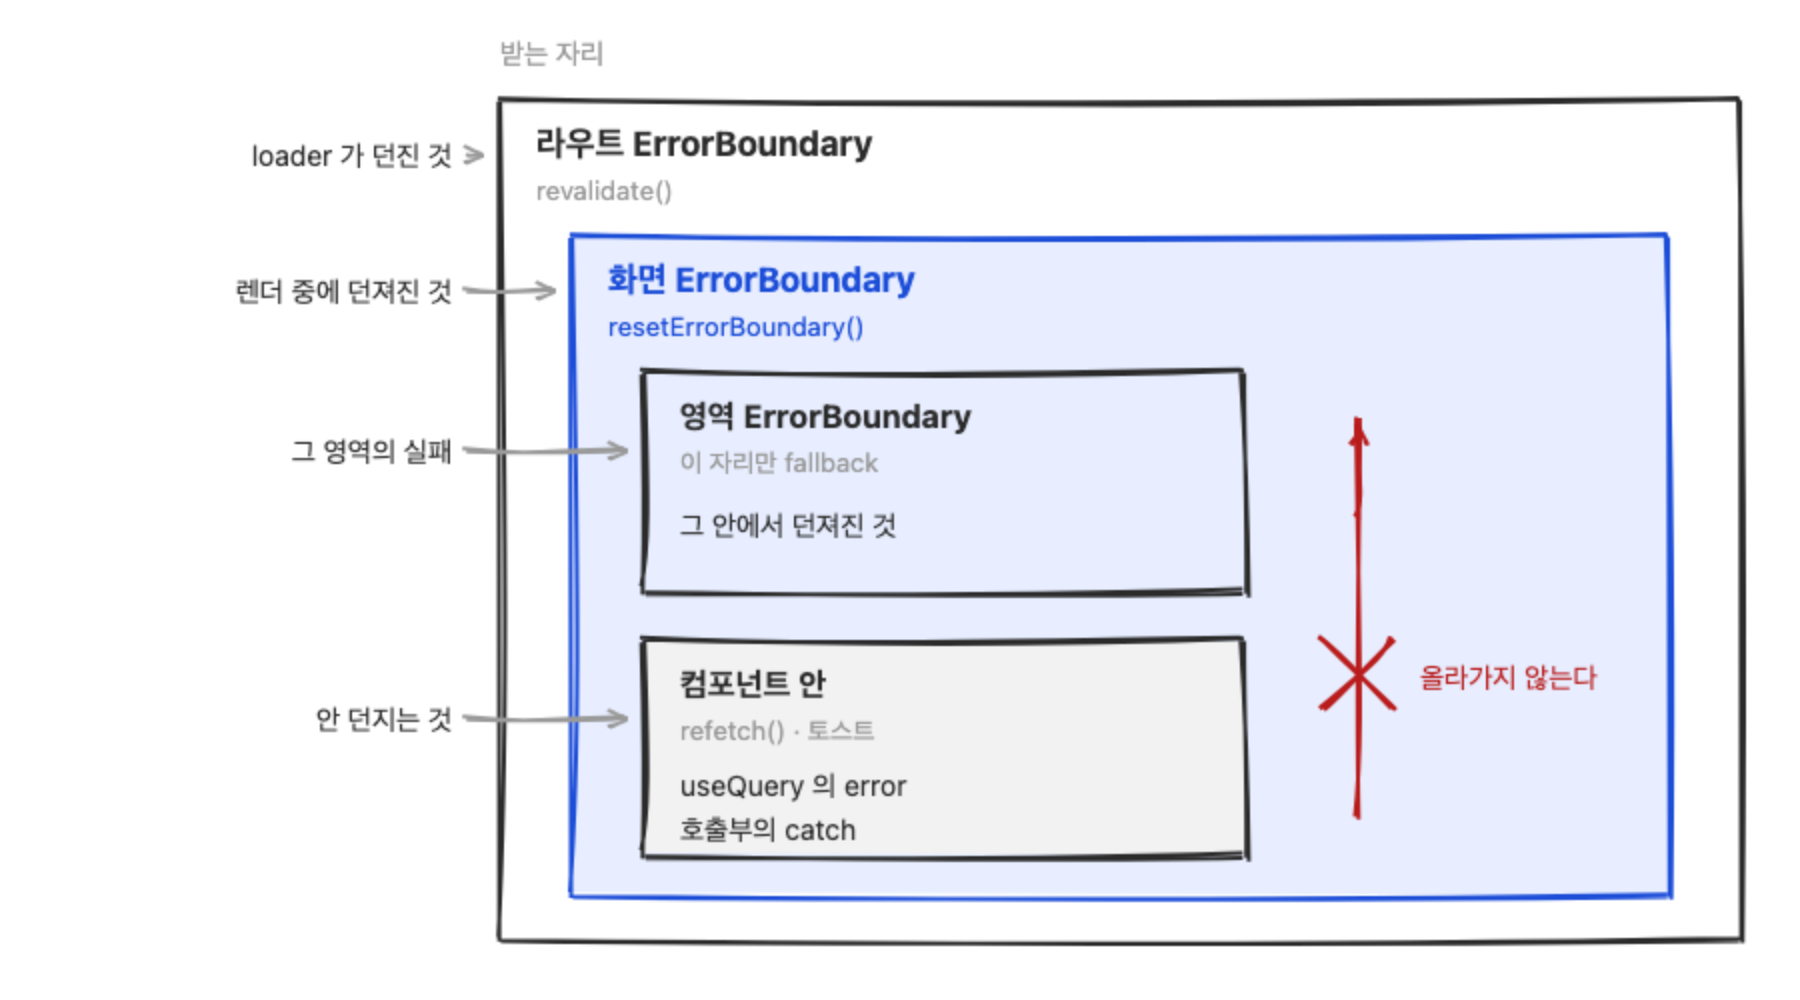
There are four names but only two kinds. Only the route ErrorBoundary belongs to the router; the other two are ErrorBoundary you place in the tree. The screen ErrorBoundary and the region ErrorBoundary are the same component, differing only in where they are attached. The bottom row, inside the component, is not an ErrorBoundary at all but a branch the component draws itself.
The sections below look at why you cannot delete any row of this table.
Three layers you cannot delete
Once you install react-error-boundary, the router's side starts to look deletable. The names match, so the jobs look like they match too. But there are three reasons you cannot delete any one of them. The three counted here are route, screen, and region from the table above. Inside the component is excluded because it is not an ErrorBoundary.
The loader lives outside ErrorBoundary
This is exactly what part 1 showed. An ErrorBoundary is a class built from getDerivedStateFromError and componentDidCatch, so only what React caught inside the tree reaches it. A loader is a function that runs outside the tree, before rendering even starts. What it throws never passes through React, so no amount of wrapping makes it visible.
That means if even one route uses a loader, you cannot delete the route ErrorBoundary. The moment you do, that failure has nowhere to go.
The cache revalidate cannot clear
The opposite direction is blocked too. The recovery mechanism of the route ErrorBoundary is revalidate(), and that only re-runs the loader. It does not touch the query cache.
Consider a route with no loader. If a useSuspenseQuery inside the screen fails, the route ErrorBoundary does end up receiving it. The router wraps the route tree in a class of its own called RenderErrorBoundary, and that class also has getDerivedStateFromError. But pressing retry in that ErrorBoundary gets you nowhere: there is no loader to re-run, and the error stuck in the cache is still there. It received the failure but has no way to undo it.
Receiving and undoing are different jobs. If you do not look at both when placing an ErrorBoundary, you end up with a fallback that catches things nobody can clear.
A lower ErrorBoundary narrows the radius
The third one is not about being blocked. It is about losing too much.
When something fails, the router picks one ErrorBoundary. The way it picks is in the source.
function findNearestBoundary(matches, routeId) {
  let eligibleMatches = routeId ? matches.slice(0, matches.findIndex((m) => m.route.id === routeId) + 1) : [...matches];
  return eligibleMatches.reverse().find((m) => m.route.hasErrorBoundary === true) || matches[0];
}
It walks the matched routes from the back, picks the first route that has an ErrorBoundary, and falls back to the very first one if there is none. If a child in a nested route has no ErrorBoundary, the parent takes that job, and if the parent has none either, the root takes it.
When the root takes it, the whole screen disappears. Only one inner region failed, yet the header and the navigation go with it. Attach an ErrorBoundary to the child route and the fallback is drawn only in the <Outlet /> slot.
So adding one more ErrorBoundary below is not duplication. It does not catch the same failure twice; it changes how much gets erased. A layout that looks like three overlapping boundaries is really three different things being received at three different radii.
Between a region ErrorBoundary and inside the component
Once the layers are split four ways, one last fork remains. For a region the screen holds together without, you choose whether to lift it into an ErrorBoundary or handle it in place.
Either way you lose only that region and keep the rest. What differs is not how much you lose but what you draw there instead.
Lifting it into an ErrorBoundary shrinks the code. Call useSuspenseQuery inside and that component has neither isPending nor isError. The outer Suspense takes the waiting, the outer ErrorBoundary takes the failure. The component only draws the case where data exists.
<section>
  <h2>댓글</h2>
  <QueryAsyncBoundary pendingFallback={<p>불러오는 중</p>}>
    <CommentList postId={postId} />
  </QueryAsyncBoundary>
</section>
In exchange, that whole region turns into the fallback. For a spot like a list, where nothing is worth keeping if the whole thing goes, that costs nothing.
Handling it in place is the opposite. You call useQuery and draw the four states (pending, failed, empty, present) yourself. The branches multiply, but in return you can put wording and actions tailored to that spot. If you want a small retry button on just the row that failed, this is the way. Lift it into an ErrorBoundary and the shape of that row gets decided by the fallback component, which is usually the one shared with the screen ErrorBoundary and is far too heavy for a single failed row.
The criterion comes out like this. If the region can vanish whole, ErrorBoundary is better; if you need wording or actions tailored to that spot, useQuery is better. An ErrorBoundary takes the branches out of your component, but it takes the freedom to decide the screen along with them.
If you decide not to lift it into an ErrorBoundary, you have to handle all four states.
const { data, isPending, isError, refetch, isRefetching } = useQuery(commentsOptions(postId))

if (isPending) return <p>불러오는 중</p>

if (isError) {
  return (
    <div role="alert">
      <p>댓글을 불러오지 못했어요</p>
      <button onClick={() => refetch()} disabled={isRefetching}>재시도</button>
    </div>
  )
}

if (data.length === 0) return <p>아직 댓글이 없어요</p>
Leave out isError and the failure quietly flows into the empty state. The data of a failed query is undefined, and a check like data == null || data.length === 0 does not distinguish that undefined from an empty array. The screen says there are no comments yet while the server is handing out a 500 at that very moment.
Filter isError out first and data narrows to an array below it, and the == null check disappears.
A different fallback per layer
Now that the layers are placed, decide what each one draws on screen. Here the route ErrorBoundary and the ErrorBoundary you place in the tree diverge again, and the criterion for choosing is not taste but how that layer is handed the error.
The route ErrorBoundary reads it itself
A route ErrorBoundary does not need the error passed down to its fallback. The component reads it directly with useRouteError() and fetches its recovery mechanism on its own.
export function RootErrorBoundary() {
  const error = useRouteError()
  const { revalidate, state } = useRevalidator()

  return <ErrorFallback error={error} onRetry={revalidate} retrying={state === 'loading'} />
}
So all a route needs is the component plugged in. A child route's ErrorBoundary has the same shape and uses the same hooks. What separates the two is not the code but the route it is attached to. Which route it sits on is exactly the radius the fallback is drawn over.
The ErrorBoundary that hands it down
In react-error-boundary, the ErrorBoundary is the opposite. It holds both the error and the reset function itself, so it has to hand them down to the fallback. That is why there are three props, and the type definition binds the three as mutually exclusive.
fallback takes a finished element as is. You write it like fallback={<p role="alert">댓글을 불러오지 못했어요</p>}. It gives you neither the error nor the reset function. It is only usable when the message is fixed and there is no way to retry anyway.
FallbackComponent takes a component and passes error and resetErrorBoundary to it as props. It is tidy when several ErrorBoundary share the same fallback, but the prop name is fixed as resetErrorBoundary, so the receiving side has to know that name.
function CommentsFallback({ error, resetErrorBoundary }: FallbackProps) {
  return <ErrorFallback error={error} onRetry={resetErrorBoundary} />
}

<ErrorBoundary onReset={reset} FallbackComponent={CommentsFallback}>
  <CommentList postId={postId} />
</ErrorBoundary>
ErrorFallback takes onRetry, so the names do not line up. That costs one more component whose only job is to move the name across.
fallbackRender takes a function and renders it right there.
<ErrorBoundary
  onReset={reset}
  fallbackRender={({ error, resetErrorBoundary }) => (
    <ErrorFallback error={error} onRetry={resetErrorBoundary} />
  )}
>
I picked this one. The reason is that you can swap the name right there. Above, resetErrorBoundary became onRetry. Thanks to that, ErrorFallback becomes a component that knows only error and onRetry, and the revalidate-backed route ErrorBoundary and the resetErrorBoundary-backed tree ErrorBoundary use the same fallback.
Two layers whose screens do not drift apart is what this choice buys. Split the layers four ways and the failure screens the user sees risk becoming four as well, and swapping one name makes them one.
Three cases where retry does nothing
I attached a retry button to the fallback. That is the button the user presses to undo a failure. Let us press it. Nothing happens. The same screen comes back unchanged.
It arises for three reasons and each is undone differently. They have one thing in common. An ErrorBoundary only undoes its own state. State held by whatever threw has to be cleared by whatever threw.
The query error reset clears
All resetErrorBoundary() does is flip the ErrorBoundary's internal flag back. The children remount and the query resubscribes. But that query is stuck in the cache in an error state. So it immediately throws the same error again and the ErrorBoundary draws the fallback again.
Why it uses the old error instead of refetching is in the source too. errorBoundaryUtils.js locks it like this.
if (options.suspense || throwOnError) {
  if (!errorResetBoundary.isReset()) options.retryOnMount = false;
}
Read the outer guard first. This lock only applies to queries that throw. A query with suspense on, or with throwOnError on, that mounts without a reset marker has its retry turned off. A useQuery that does not throw is unaffected and simply refetches when it remounts.
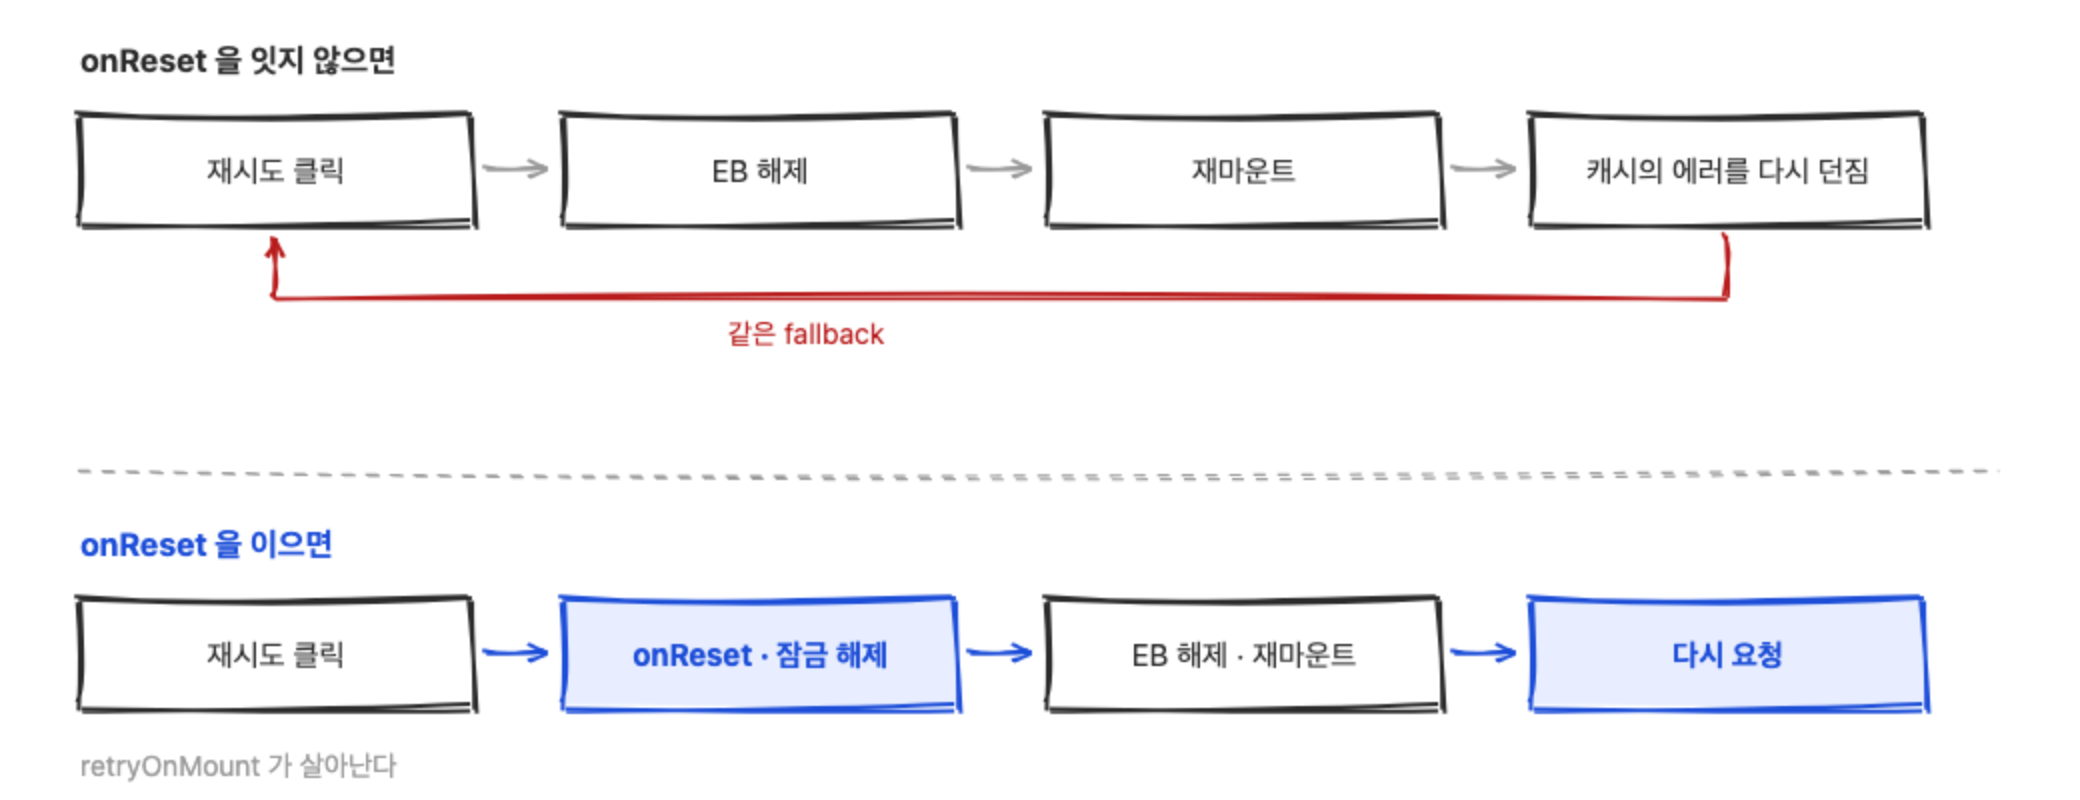
What gets locked is only a query lifted into an ErrorBoundary, and that is why you have to clear both states together. What raises that marker is QueryErrorResetBoundary. Open the source and the state is a single boolean.
reset: () => {
	isReset = true;
},
You wire this reset to the ErrorBoundary's onReset. TanStack Query's docs and source comments carry the same wiring as an example.
export function QueryAsyncBoundary({ children, pendingFallback }: Props) {
  return (
    <QueryErrorResetBoundary>
      {({ reset }) => (
        <ErrorBoundary
          onReset={reset}
          fallbackRender={({ error, resetErrorBoundary }) => (
            <ErrorFallback error={error} onRetry={resetErrorBoundary} />
          )}
        >
          <Suspense fallback={pendingFallback}>{children}</Suspense>
        </ErrorBoundary>
      )}
    </QueryErrorResetBoundary>
  )
}
Order matters. And react-error-boundary guarantees that order. It is a built file so the names are down to one letter, but the structure still reads.
resetErrorBoundary(...e) {
  const { didCatch: t } = this.state;
  t && (this.props.onReset?.({ args: e, reason: "imperative-api" }), this.setState(d));
}
They are joined by a comma operator, so onReset runs first and setState comes after. d is the initial state where didCatch is false. So the children remount after the cache lock has been released. One line of difference is what turns retry into an actual retry.
Putting Query in the name is deliberate too. Call it AsyncBoundary and it reads as usable for any async work, which it is not, because QueryErrorResetBoundary sits inside it. For the same reason I gave pendingFallback no default value. With a default, a single line at the call site does not tell you what gets laid down.
The render error reset cannot clear
The second one is the case from part 1. The server returns a 200 with a shape other than the one you expected, and the render that reads it throws a TypeError. The same ErrorBoundary received it and onReset is wired, yet retry does nothing.
What reset clears is a query in an error state. But this query succeeded. The server gave a 200 and the cache holds that value as normal data. What produced the error is the render that read it. So reset has nothing to clear, and the remounted component gets the same cache, still within staleTime, and throws again on the same line.
The place to fix it is queryFn.
queryFn: async () => {
  const data = await getComments(postId)
  if (!Array.isArray(data.comments)) {
    throw new TypeError('comments 가 배열이 아니다')
  }
  return data.comments
},
Part 1 said the place where types end is the place to put a runtime check. That place is here. Lift that check up into queryFn and the same failure becomes the query's error. It stays in the cache in an error state, reset clears it, and retry refetches.
If you put the runtime check off because the ErrorBoundary catches it anyway, you get a fallback that receives but cannot undo.
The lazy only a reload clears
The third is a chunk load failure. This time neither reset nor queryFn is involved. What holds the state is lazy itself.
As part 1 showed, React's lazyInitializer writes the rejection into payload and from then on throws the same thing every time.
throw payload._result;It does not import() again. The lazy() call happened once at module top level, and that payload stays as it is for the life of the app. Release the ErrorBoundary and remount, and the same error comes back.
So recovering from this failure means fetching the page again. It also means a new version has been deployed, so it is better to tell the user exactly that.
Put the three cases together and one retry button has to do three different jobs. A query error is cleared with reset, a render error by turning it into a query error up in queryFn beforehand, a chunk failure by reloading. The ErrorBoundary does none of them for you.
Failures you do not attach retry to
Now that recoverable and unrecoverable failures are separated, the button has to be separated too.
Showing the same button on every failure means guiding the user toward an action they cannot take. Press retry on a 404 and you get the same 404. A 403 from missing permissions is the same. A chunk load failure does nothing at all, for the reason in the previous section.
Splitting it once inside the shared fallback is enough.
function describe(error: unknown) {
  if (isChunkLoadError(error)) {
    return { title: '새 버전이 배포됐어요', description: '새로 고침하면 이어서 볼 수 있어요.', action: 'reload' }
  }

  const status = isHttpError(error) ? error.status : isRouteErrorResponse(error) ? error.status : undefined

  if (status === 404) {
    return { title: '찾을 수 없어요', description: '주소가 바뀌었거나 삭제된 항목이에요.', action: null }
  }
  if (status !== undefined && status >= 400 && status < 500) {
    return { title: '요청을 처리할 수 없어요', description: '입력한 내용을 다시 확인해 주세요.', action: null }
  }
  return { title: '불러오지 못했어요', description: '잠시 후 다시 시도해 주세요.', action: 'retry' }
}
There is a reason isRouteErrorResponse is in here too. The route ErrorBoundary and the ErrorBoundary in the tree share a fallback, so this function receives both kinds of error. Reading the status code off a Response the router threw and reading it off an HTTP error you built yourself work differently, so it checks both.
You do not need a huge branch from the start. Separating failures that will come out differently when pressed again from those that will not is enough.
When the ErrorBoundary sees the failure
The ErrorBoundary are all placed, and one thing is still missing. When does an ErrorBoundary see anything?
The layers were decided top down, but the execution order is the reverse. The ErrorBoundary sees something only after every retry has been exhausted. So the retry condition is part of designing the ErrorBoundary.
The default differs per place. Both use the same createRetryer, but they pass different values into it. A query passes nothing and takes the default from retryer.js.
const retry = config.retry ?? (isServer() ? 0 : 3);A mutation puts 0 in directly, in mutation.js.
retry: this.options.retry ?? 0,A mutation at 0 means that once a request ends in an error, the action fails right away. No retries for actions that are hard to undo is a safe default, but if the action is idempotent, sending it once more is better for the user.
Stating the same condition on both sides is better.
const MAX_RETRY = 2

export function retryOnServerError(failureCount: number, error: unknown): boolean {
  if (failureCount >= MAX_RETRY) return false
  return !isHttpError(error) || error.status >= 500
}
failureCount starts at 0 and asks with 0 on the first failure. So with MAX_RETRY at 2 it sends three requests in total and stops. It is a retry count, not an attempt count.
Excluding 4xx is the key part. The request itself is wrong, so the same answer comes back however many times you send it. But waste is not the only reason to exclude them. The default delay grows exponentially.
function defaultRetryDelay(failureCount) {
	return Math.min(1e3 * 2 ** failureCount, 3e4);
}
The first retry is 1 second and the next is 2, so two retries alone burn 3 seconds. Fail to filter out 4xx and you are hiding an unfixable failure for 3 seconds.
Render errors and chunk failures have no such delay. No request goes out, so there is no retry at all, and the ErrorBoundary sees it the moment it is thrown. This is why the same fallback appears 3 seconds later for some failures and immediately for others.
There is one premise to confirm before turning retries on. Is that request idempotent? Sending the same request twice has to produce the same result. If the server does not guarantee that, retrying is a feature that manufactures bugs.
Wrapping up
Part 1 covered where errors go, and this post decided what to put in those places. To summarize:
- The position of an
ErrorBoundaryis decided by the blast radius you can afford. You ask not what to wrap, but what has to remain when this dies. - You cannot delete any of the three layers of
ErrorBoundary. What the loader threw cannot reach theErrorBoundaryin the tree,revalidatecannot clear the query cache, and adding one more below narrows the radius. - If the region can be thrown away whole,
ErrorBoundary; if you need wording specific to that spot,useQuery. Choose the latter and you have to handle all four states. - Swap the name with
fallbackRenderand the fallback becomes one even across different layers. - Retry works only once you clear the state held by whatever threw. A query is
reset, a render error is lifted intoqueryFn, a chunk is a reload. - When an
ErrorBoundarysees the failure is decided by the retry condition. Fail to filter out 4xx and you hide an unfixable failure for seconds.
You could ask whether one ErrorBoundary and a toast are not enough. For a product with two or three screens that is a fair point, and in fact the number of layers is decided by the product. If there is only one screen, there is only one screen to give up, so differences in radius are invisible. The more independent regions there are inside a screen, the larger that difference gets.
Something survives regardless of the number, though. However many ErrorBoundary you put in the tree, what loader threw does not go there, and retry does nothing unless you clear the state held by whatever threw. What you can reduce is the layers, not these facts.