Decision Models, Jev and Kev
In this post, I want to talk about a model that produces no text. Last week TypeSafe AI released Jev.
The first use that caught my eye was browser automation. Browserbase opened a PR that wires Jev into Stagehand's act(). The page's accessibility tree goes in as state, and the question "which element should be clicked next" is asked as a set of options. Across 40 tasks the median act() latency dropped from 1.97 seconds to 0.46, and of 147 actions only 4 fell back to an LLM. The spot where a Playwright script breaks the moment one selector changes was filled with a call that returns a single probability. As I write this, the PR has not been merged.
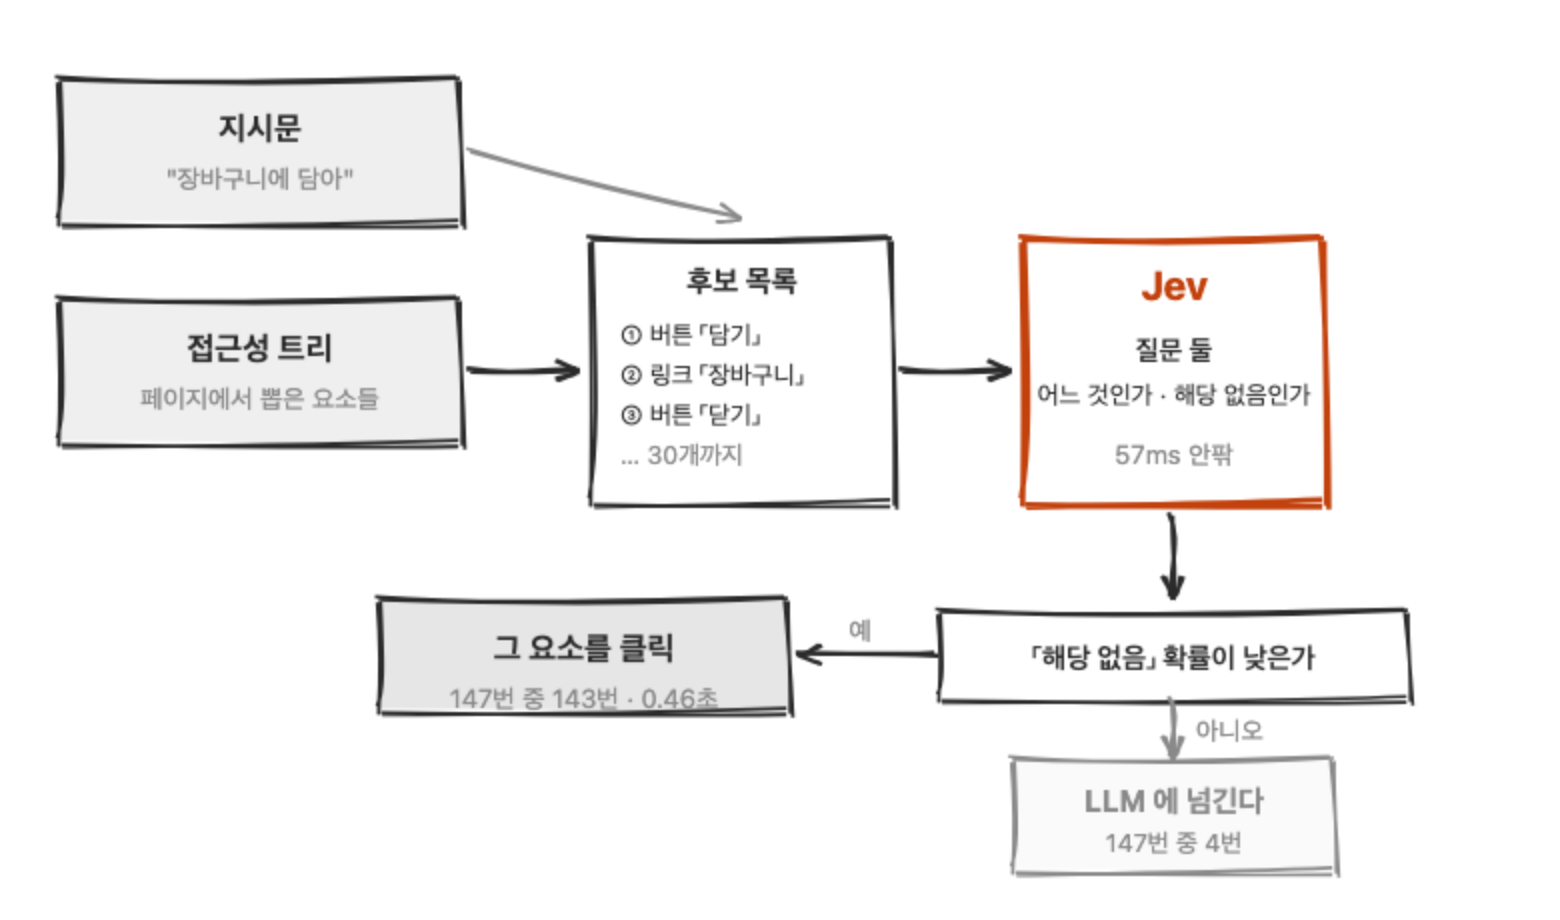
The line that PR drew is the question of this post. It accepts Jev's answer at a probability of 0.7 and hands anything below that to an LLM. Can you trust the probabilities that model returns and draw a line in your code?
Someone else's benchmark cannot settle that, so I want to verify it on my own data. This blog has a gate that blocks transliterated loanwords. The rule says to write 피커 as picker, but the regular expressions only catch the half that is certain, and words that sit inside a compound or are already settled in Korean, like 멀티스레드 or 콜 스택, I judge by hand every time. There are only two answers, revert or keep, anyone who knows decides in a second, and the pass or fail has to be decided inside a build script with no human checking. It has the same shape as Stagehand's selector decision.
So the order is this. What Jev returns, what kind of training produces that probability, what numbers come out when I hand it my gate, and where those numbers can be used.
A model that produces no text
The release date was September 15, 2026. The company does not call it an LLM; it calls it a System One Model, a new category. In this post I call them decision models. Founder Diogo Almeida was the fourth author of the InstructGPT paper at OpenAI. He was on the team that built the method that became ChatGPT's direct ancestor, and he now stands on the side that points out that method's limits.
Jev does not generate sentences. You fix the shape of the answer in advance, and it picks from that shape and returns probabilities along with it. There are only three question types.
| Type | What it asks | What it returns |
|---|---|---|
choice |
Which one of these is it | The choice, probabilities, confidence |
score |
At what level is it | The score, legend, probabilities, confidence |
noul |
Is it true | A single probability between 0 and 1 |
There is only one endpoint, too. Send a POST /v1/systemone with state, the thing to evaluate, model, and questions, a map of questions, and the answer comes back. You can pack several questions about the same state into one request, and adding questions barely increases the response time.
Why it is fast is explained by the asymmetry between prefill and decode that I laid out in how tokens work. An LLM is slow because it squeezes its output out one token at a time, sequentially, and Jev has no decode stage. It reads the input once in parallel and reads the probabilities straight off. So there is no output token charge at all, and input alone costs $0.042 per million tokens.
A developer named Archer Hume called the API roughly ten thousand times and reconstructed its behavior from the outside in an analysis. The median was 57.5ms for 360 input tokens, 218ms for 29,835 tokens, and 610ms when he packed in 1,500 questions. The most direct piece of evidence there is his observation that a response with 200 choices came back as fast as one with 2. It means writing the answer takes no time.
Decisions nobody watches
The speed and the price stand out, but the question Almeida raised in the launch post pointed elsewhere. Models have been superhuman at conversation for years now, so where did all the automation go?
His answer is that the two kinds of work are different. Chatbots, copilots, and coding agents have the goal of satisfying a person watching from beside you. A judgment that runs quietly on a server with nobody watching does not. If you call the former assistant and the latter automation, every model released so far was built for the former.
I drew a similar distinction while writing up harness design. An agent system contains countless judgments nobody looks at. Should this request be handed to a human? Is this command safe to run? Right now we put all of them to an expensive LLM. The other half that my regular expression gate cannot cover is that kind of judgment too.
What RLHF left behind
But why did this call for a new training method? Could you not simply make an existing model answer yes or no?
The answer is in the lineage of RLHF (reinforcement learning from human feedback). The skeleton of building a reward model out of human preference comparisons came from Christiano et al.'s 2017 paper, Stiennon et al. applied it to language models in 2020, and InstructGPT extended it to instruction following. The three papers share a single objective function. Produce the output a human rater prefers.
Here you have to separate accuracy from calibration. Accuracy is what percentage you get right; calibration is whether you know what percentage you will get right. If you gather only the days a forecast said a 70% chance of rain and it actually rained seven times out of ten, that forecast is well calibrated. That does not mean it is accurate. It means it knows its own limits. A model that gets only 60% right scores full marks on calibration if it says 60% about itself.
The metric for that gap is ECE (expected calibration error). For each probability bin it takes the difference between the "stated probability" and the "actual hit rate," weights it by that bin's share of the samples, and averages; 0 is perfect.
For a chatbot, human preference is the right objective. The trouble is that people prefer a confident answer to a hedging one. So the model picks up the habit of speaking decisively even when things are ambiguous. The TypeSafe documentation calls this mode dropping: preference optimization pushes the model toward favoring a particular style and suppresses the probability of the other possible outputs.
OpenAI wrote the same thing in its own report. Figure 8 of the GPT-4 technical report places the calibration curves of the pre-trained model and the post-trained model side by side, and the caption reads:
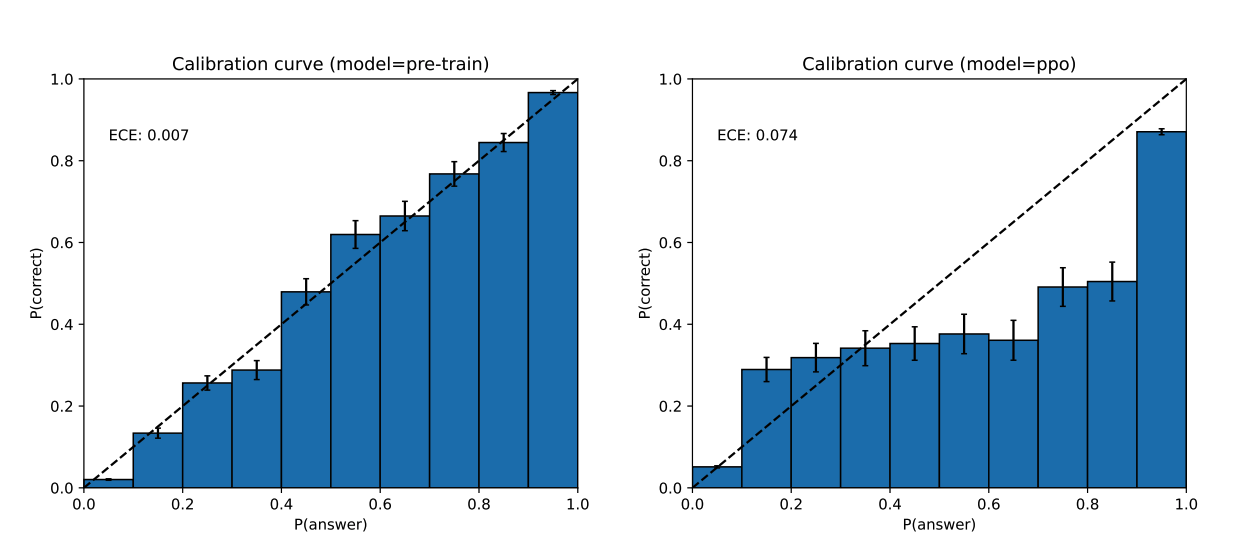
Source: OpenAI, GPT-4 Technical Report (arXiv:2303.08774), Figure 8.
Right: Calibration plot of the post-trained GPT-4 model on the same subset of MMLU. The post-training hurts calibration significantly.
By the numbers printed on the figure, the pre-trained model's ECE is 0.007 and the PPO-tuned model's is 0.074. More than ten times worse. The ability to know what percentage it would get right was shaved off in the course of being polished to satisfy people.
ECE alone is not enough, though. A constant predictor that stamps 0.6 on every input also has an ECE of 0 as long as its real hit rate is 60%. If the probabilities are merely honest and do not separate from case to case, there is nowhere to draw a line. So alongside calibration you have to watch whether the probabilities actually separate, and the "share that can be automated inside an error budget" I use later on is the metric that folds those two into one number.
From a software point of view, this is the part that matters. If the probabilities are honest and they separate, you can draw a line. You get a structure where anything above 0.95 is handled automatically and anything below goes to a person.
TypeSafe says it opened a third road aimed at that spot: RLHF, which optimizes human preference; RLVR (reinforcement learning with verifiable rewards), which optimizes answers a machine can grade; and RLCD, which it says optimizes calibrated decisions.
What has actually been published as RLCD, though, is three lines of output contract. As of September 23, 2026, when I am writing this, there is no paper or technical report anywhere in TypeSafe's documentation or launch post. There is a separate ICLR 2024 paper using the same acronym, but that one is reinforcement learning from contrastive distillation, a different method. Take care not to mix them up when searching.
What confidence really is
So, are the numbers Jev returns honest? Before answering, there is something to look at first. It does not return one number.
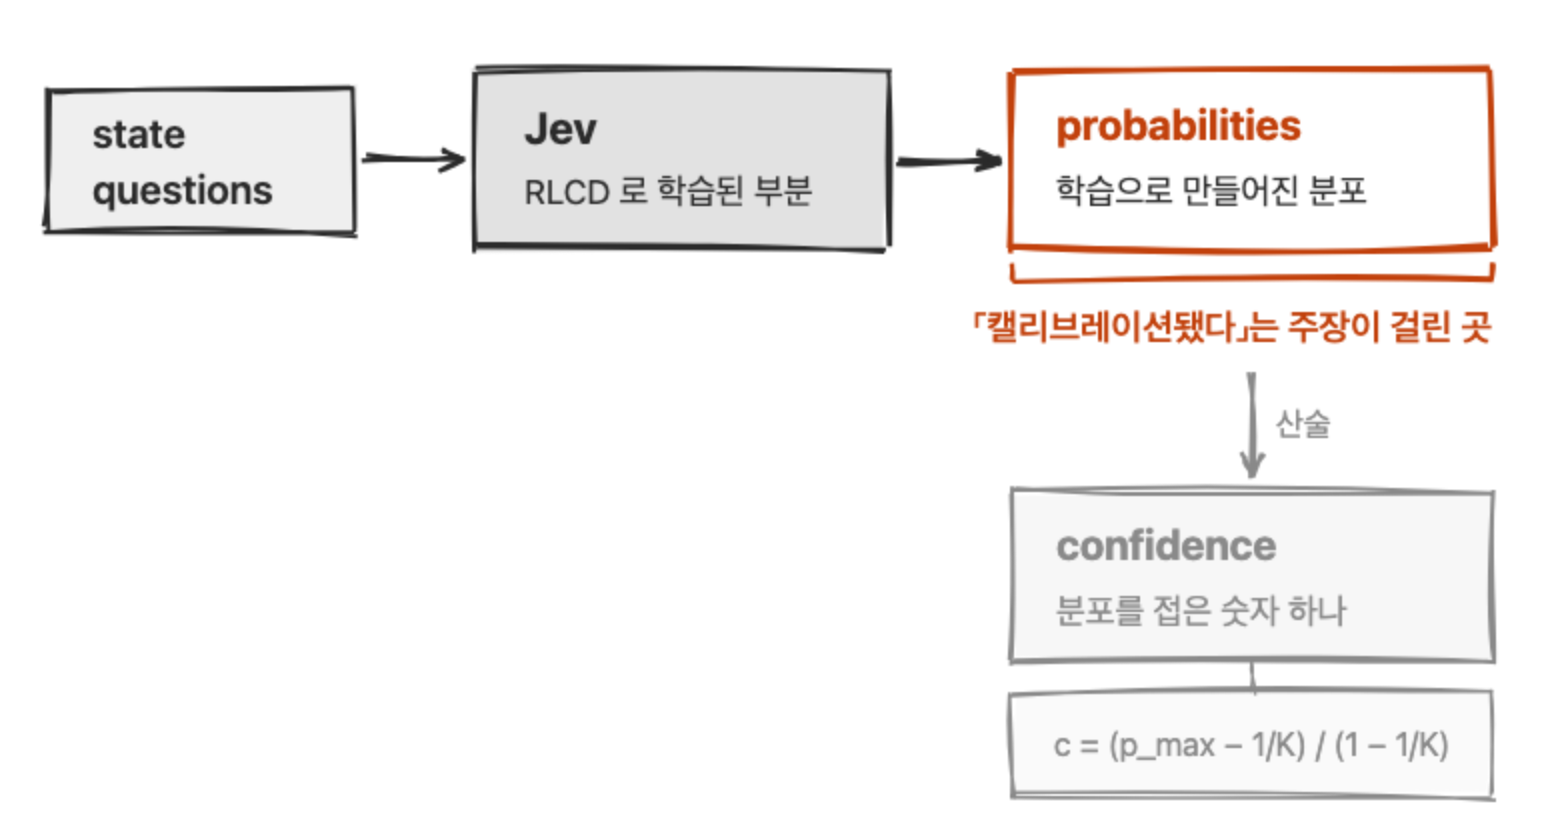
Choice and Score responses carry both probabilities and confidence. The first is a probability distribution across all the options, the second a single number between 0 and 1. When you set a threshold in code, the one your hand reaches for first is confidence.
This value is not something the model produced. _utils/confidence_metrics.py in system-one-adapter-python, published by the TypeSafe organization, is 32 lines in total, and the Choice part looks like this.
def choice_confidence(probs: list[float]) -> float:
    """Scale peak choice probability from uniform to certainty."""
    if len(probs) == 1:
        return 1.0

    normalized_probs = _normalize(probs)
    uniform_probability = 1.0 / len(normalized_probs)
    return (max(normalized_probs) - uniform_probability) / (1.0 - uniform_probability)
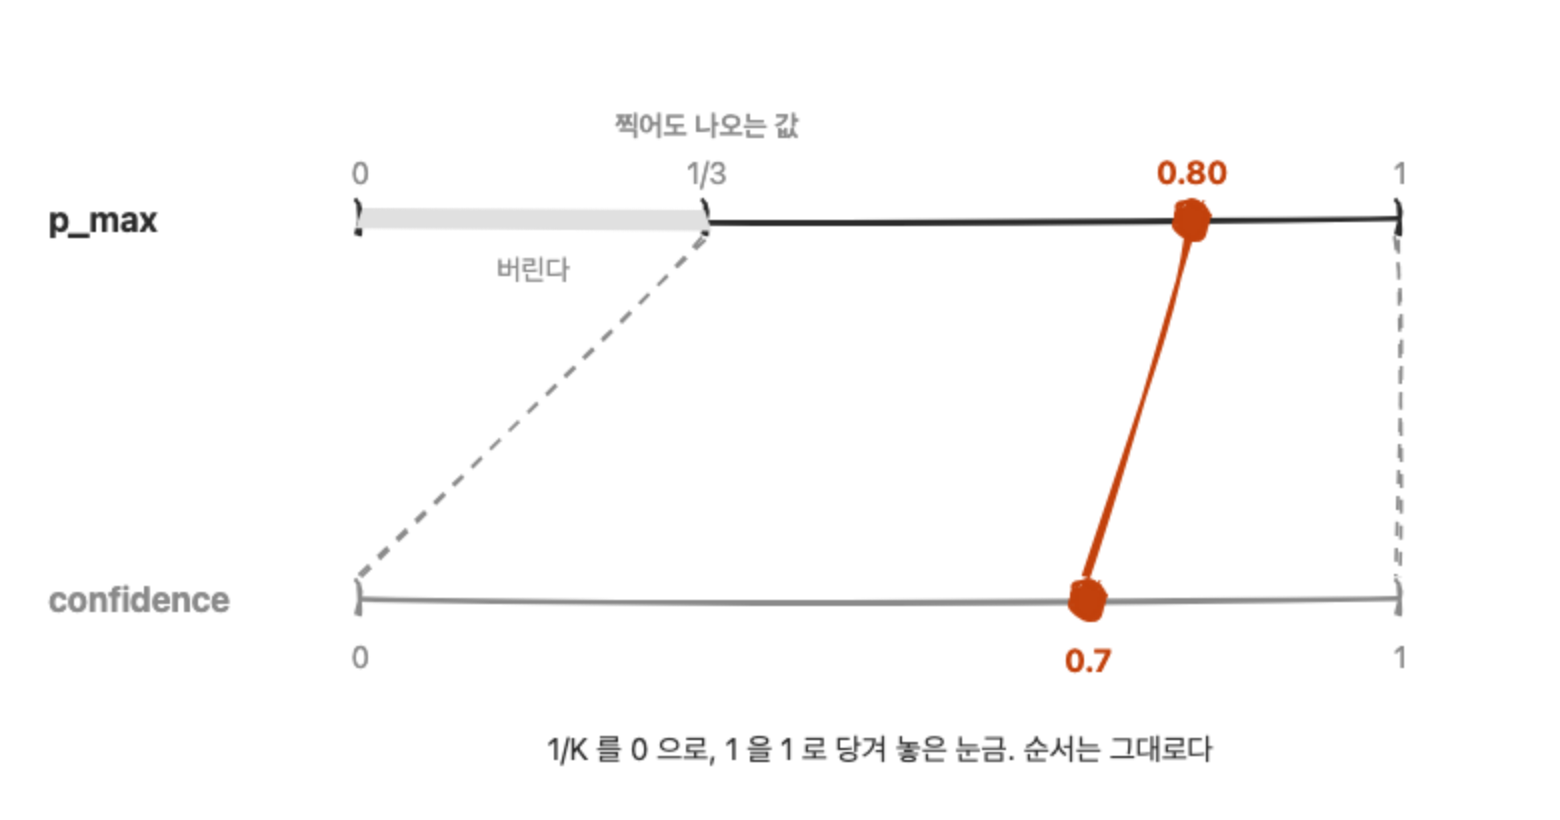
There is no model call and no learned parameter. One probabilities vector goes in and one real number comes out. Written as a formula it is c = (p_max − 1/K) / (1 − 1/K), and with three options and a peak probability of 0.8 it comes to 0.7.
This repository is not the production Jev server but a substitute implementation that imitates the same API with an LLM. So this alone cannot settle it. There are, however, two further pieces of evidence pointing at the same formula. The confidence page of TypeSafe's official documentation describes this value as "a statistic computed from the probability distribution" and, in its demo code, gives (3 × largest probability − 1) / 2 as an approximation for three options. With K at 3, that is the formula above. And a claims audit ledger recorded that on the real API, when the winner of a response given only two options that were both wrong was 0.52, confidence came back as 0.04. With a K of 2, (0.52 − 0.5) / (1 − 0.5) = 0.04. It matches the formula.
In the same repository, Score uses an entirely different formula. It divides the mean absolute distance from the modal level by the same quantity for a uniform distribution and then subtracts the result from 1. The documentation does not publish the formula for Score. So there are two formulas under the single name confidence, and with a different type the same number means something different. Noul having no confidence is for the same reason. There is no distribution to fold.
The documentation does not hide this either. It goes as far as telling you that if you want a different calculation it will hand you the whole probabilities and you can do as you like. It is written down, and the problem is on the side that uses it without reading.
The comparison table in the launch post, however, puts the two right next to each other. It says "Calibrated: higher confidence means higher accuracy." The reader takes that to mean confidence is the calibrated value, whereas the side the calibration claim actually attaches to is probabilities.
There is a measurement of how far this distinction opens up in numbers. An independent calibration measurement published by a developer called scienthoon separately measured the ECE you get when you read confidence as "the probability of being right." It is 0.035 on OpenBookQA, 0.078 on HellaSwag, and 0.18 on a synthetic set. The raw probabilities on the same sets were 0.024, 0.029, and 0.107 respectively. On all three sets the confidence side is worse.
Why it gets worse is in the formula. With K fixed, c is a monotonically increasing transform of p_max, so the ordering is preserved. Discriminative power stays the same, and you only rewrite the threshold. What breaks is not the information but the scale. If K differs from question to question, one more problem appears. The stretching factor differs too. The same p_max of 0.8 becomes 0.6 with two options and 0.75 with five. The moment you use a single threshold on a workload with mixed option counts, that becomes a problem.
Calibration that shifts with the distribution
So can the probabilities side be trusted?
There is a published record of someone actually calling Jev and measuring. The repository for Kev, an open source reimplementation built by Jared Palmer, has a runs/jev-* directory, and usage.json records with "model": "typesafe-ai/jev" that these were real calls made through the Vercel AI Gateway. Adding up the six jev-* directories' usage.json files, across September 18 and 20, 2026, it made 5,364 calls on 2,418,260 input tokens. Of the seven sets below, scienthoon was imported by converting that developer's result files, so it is not in this total.
That the pricing really charges for input only is confirmed elsewhere. The author of the phishing benchmark looked at the TypeSafe dashboard and wrote it down. Of the 4.56 million tokens across two runs, 3.66 million were input and 900,000 were output, and the bill was $0.15, which matched the figure you get by counting input alone.
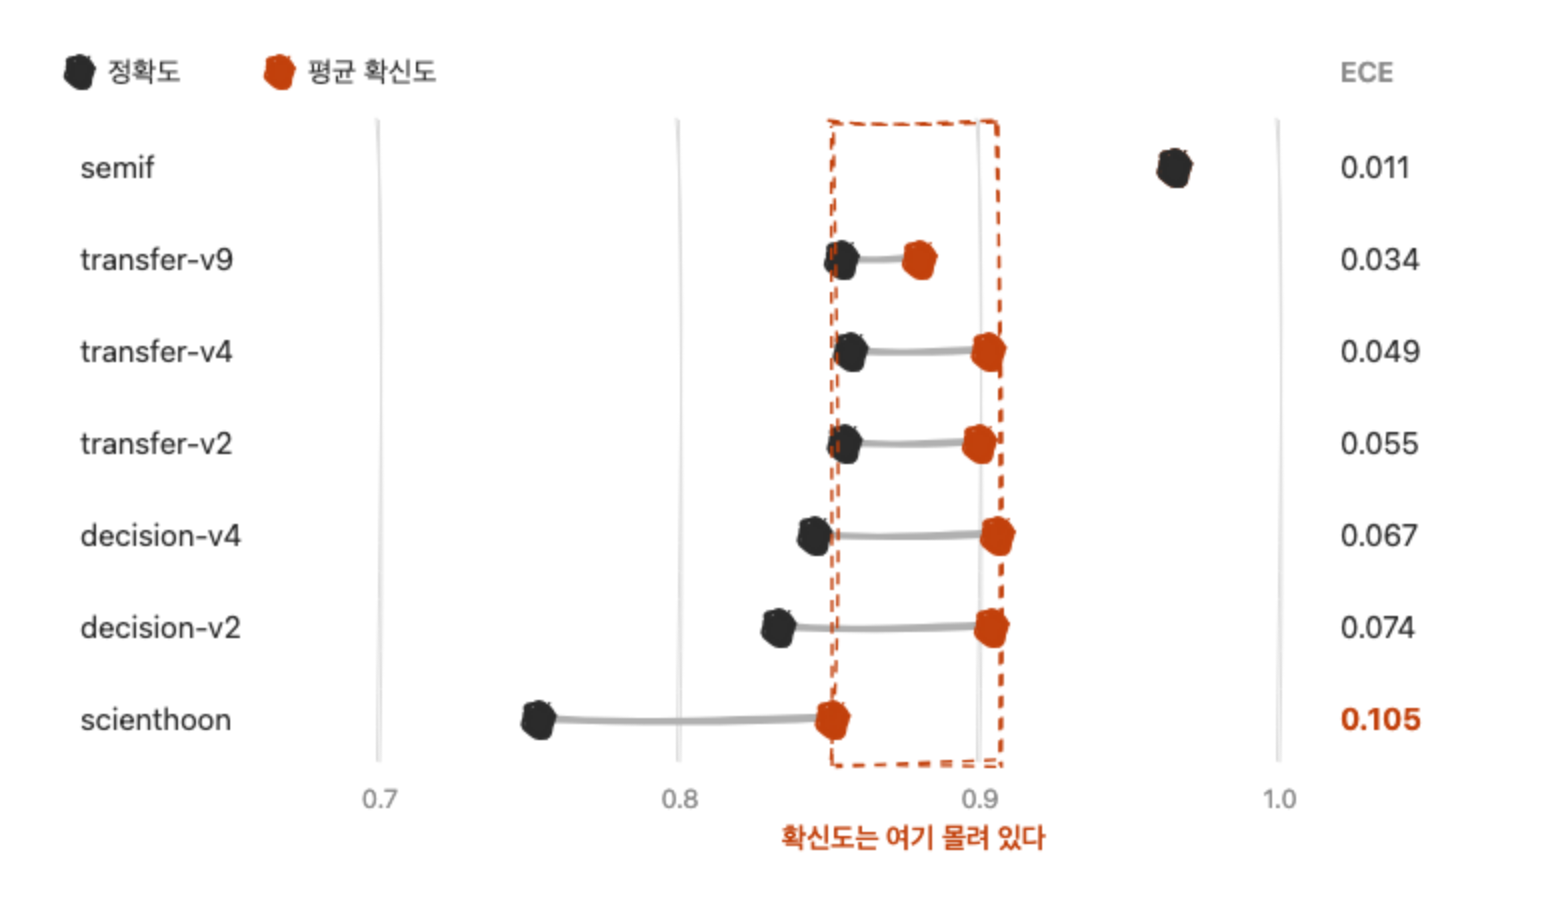
Pulling the metrics for seven evaluation sets out of report.json in the same directory gives this. Below, peak probability is not the confidence field but the maximum of probabilities. Overconfidence is 평균 확신도 − 정확도, mean peak probability minus accuracy, over 5,743 items in total. The values come from the clean block, which excludes from accuracy scoring the "unknowable" items whose grounds for judgment were erased.
| Evaluation set | n | Accuracy | Mean peak probability | Overconfidence | ECE |
|---|---|---|---|---|---|
| semif | 144 | 0.965 | 0.965 | -0.000 | 0.011 |
| transfer-v9 | 1,046 | 0.854 | 0.880 | +0.026 | 0.034 |
| transfer-v4 | 656 | 0.857 | 0.903 | +0.046 | 0.049 |
| transfer-v2 | 560 | 0.855 | 0.900 | +0.045 | 0.055 |
| decision-v4 | 1,264 | 0.845 | 0.906 | +0.061 | 0.067 |
| decision-v2 | 1,200 | 0.833 | 0.904 | +0.071 | 0.074 |
| scienthoon | 873 | 0.753 | 0.851 | +0.099 | 0.105 |
Two things read out of it.
First, the ECE moves by nearly ten times. From 0.011 to 0.105. Same scorer, same model. "Calibrated" is not a property of the model but a relation between the model and the distribution. That calibration collapses when the distribution shifts is itself a known result. What is new here is that the same shape appears even in a model that puts calibration forward as its training objective.
The 0.105 of the set with the largest ECE is bigger even than the 0.074 of the post-RLHF GPT-4 seen earlier. But you must not read these two as a ranking. The tasks differ, and ECE is an estimator whose value moves with how many bins you split into and which bins the samples pile up in, so placing numbers from different scorers side by side does not make a valid comparison.
Second, the measured ECE is almost entirely explained by overconfidence alone. The difference between the two columns runs from 0.002 to 0.011 for all seven. ECE is a weighted average of per-bin gaps, so it cannot be smaller than the overall overconfidence, and that difference being nearly 0 means the sign of the error in each bin leans one way. It is not noise that crosses over and cancels bin by bin.
Reading down the columns shows why. Leave out semif and six of the mean peak probabilities sit packed between 0.851 and 0.906. Over the same stretch accuracy moves twice as wide, from 0.753 to 0.857. Peak probability barely moves when the distribution changes, and only accuracy moves. The difference left over is the ECE.
Another benchmark shows how this property surfaces in practice. In a measurement on 2,000 phishing emails with Claude Haiku 4.5 as the control, Jev's accuracy was 62.6% and Haiku's was 81.3%. More striking, though, is the ECE. The repository reports an ECE of 0.154 for Jev and 0.097 for Haiku, and when the claims audit ledger re-bins Jev's P(phishing) values into 10 bins from 0 to 1, it comes to 0.170. Read either way, a model that puts calibration forward as its training objective lost on calibration to an LLM built with RLHF. The same author got 91.6% from the link host list rule alone.
Looking at the same metric across several sets makes the spread plainer. The share that can be handled automatically at a 5% error budget is 0.486 on the scienthoon set, 0.695 on transfer-v9, and 1.000 on semif. Kev's scorer notes that this value is the maximum with the threshold chosen inside the sample, not an error guarantee after deployment. You must not cite any one of them as if it were the model's spec.
The transliteration gate
Reading someone else's benchmark and measuring on my own data are different things. So I put the gate from the opening through it for real.
I do not have a Jev API key yet. Instead I ran Kev-9B locally, the reimplementation mentioned above. It puts a rank-16 LoRA and a pointer head on Qwen3.5-9B-Base, and it is Apache-2.0. The numbers below are not Jev's numbers. Kev's training data is English decision tasks, and in the same author's measurements Kev-9B trails Jev even on English tasks. Its automation share at a 5% error budget is 0.45 to 0.57 against Jev's 0.70, and on MMLU-Pro it is 0.52 against 0.84. The TypeSafe documentation also states, about Jev, that English is the primary training language and CJK is not equivalent.
The evaluation sets were drawn from 18 Korean posts in this repository. The ground truth for a label is which spelling this repository consistently uses for that word. That means it is this blog's convention rather than a consensus of the Korean technical writing community, and on words where the two diverge the model can be right by the community standard and wrong by this one.
- The gate set, 102 sentences. These are words the gate already knows. The positives are 23 counterfactual sentences in which words the body writes in English, such as
calendar,picker, andadapter, were turned back into Korean transliterations; the negatives are 79 sentences that actually use the exceptionswrite-post.mdspells out, such as리렌더링and콜 스택. On this set the current regular expression gate is right 100% of the time by definition. - The held-out set, 60 sentences. These are words the gate has never seen. This is what machine learning calls a held-out set. The positives are 30 sentences that turn
loader,mutation, andprefill, which the body writes only in English, back into transliterations; the negatives are 30 sentences with리듀서,스냅샷, and런타임, which the body writes only in Korean. Here the regular expressions catch none of the positives.
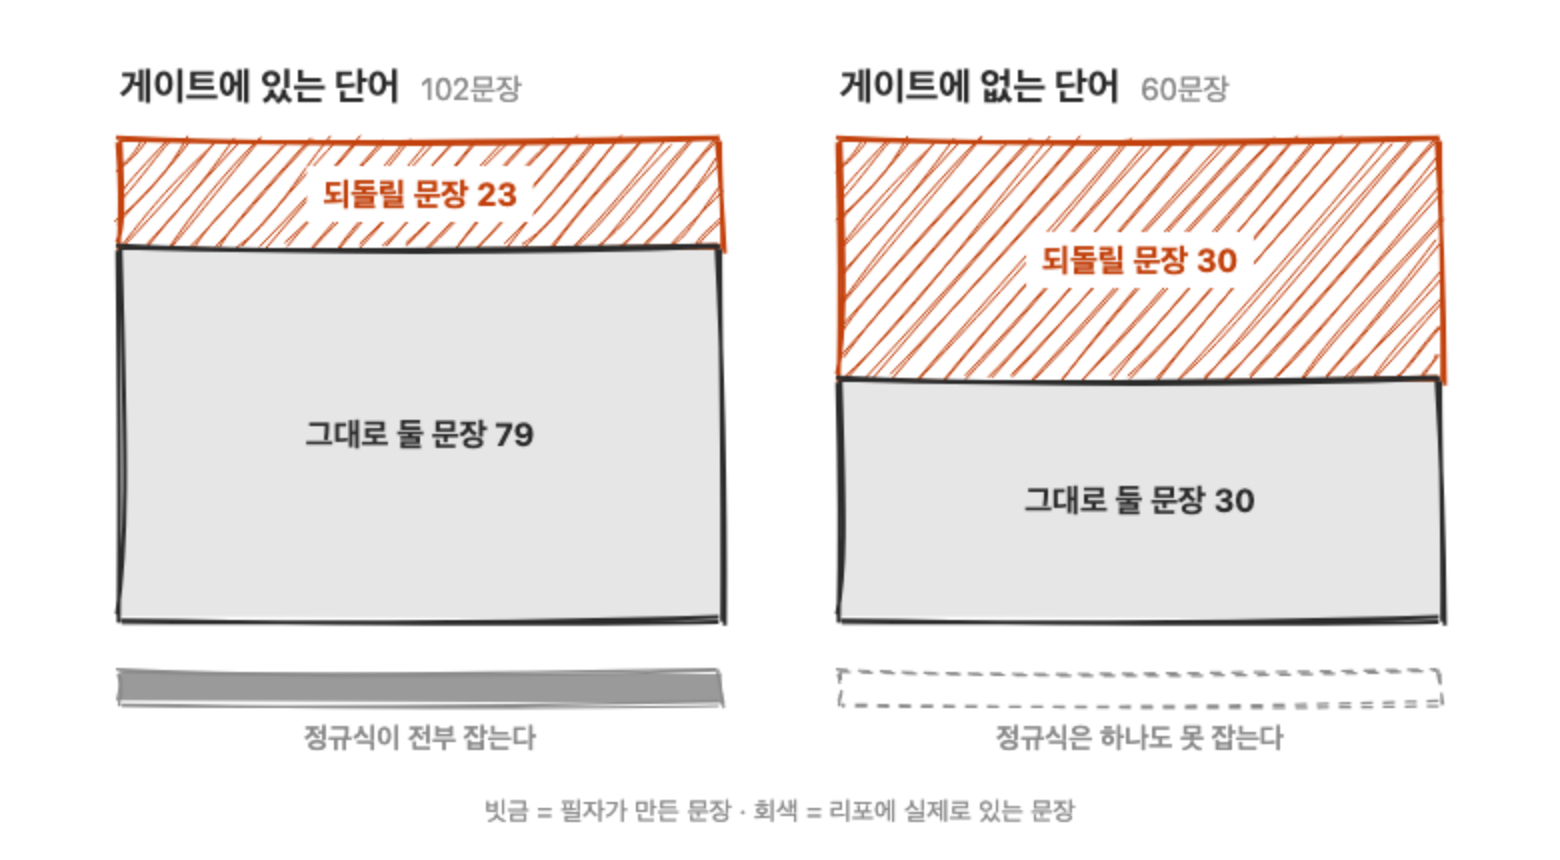
Let me disclose up front the asymmetry that the positives are counterfactual sentences I built while the negatives are real sentences. And the effective sample is the number of words, not the number of sentences. Labels are decided per word, so sentences containing the same word are not independent observations. The gate set has 24 distinct words and the held-out set 13.
The table below tallies only the one noul question asking "should this word be turned back into English." I put four questions in the same request, but the other three were a negated form, a Choice variant, and a compound-word judgment whose labels I could not set properly, so they are not mixed in here. The 5% budget automation share is the largest share you get by cutting down from the highest peak probability such that the error above the cut does not exceed 5%.
| Gate set | Held-out set | |
|---|---|---|
| Sentences / distinct words | 102 / 24 | 60 / 13 |
| Current regex gate | 1.000 | 0.500 |
| Kev-9B accuracy | 0.225 | 0.500 |
| Word-level accuracy | 6/24 | 7/13 |
| Majority class baseline | 0.775 | 0.500 |
| ECE | 0.664 | 0.336 |
| Mean peak probability | 0.876 | 0.821 |
| Share at peak probability 0.9 or above | 0.490 | 0.317 |
| Actual hit rate in that band | 0.240 | 0.526 |
| 5% budget automation share | 0.010 | 0.000 |
The majority class baseline is the score you get by never reading the sentence and stamping the more common label. The model sits below it.
The last row is this experiment's answer. On the held-out set, no matter how high I set the threshold, there was not a single decision that could be handled automatically within a 5% error.
The prediction distribution shows what happened. The model answered "it should be turned back" on all 162 sentences. All 37 distinct words. Every positive right and every negative wrong. So the 0.500 on the held-out set is not skill; it is a number that comes from the set being balanced.
And while doing that, its mean peak probability was 0.876. On the gate set, 49% came in above a peak probability of 0.9, and the actual hit rate in that band is 0.240.
The structural identity did not hold either. Adding the probabilities for "should it be turned back" and "should it be left as is" gave a mean of 1.655 on the gate set, and all 102 sentences deviated from 1 by more than 0.1.
That is by design. The two questions are separate evaluations that cannot read each other, and TypeSafe itself put an example on its jaggedness page where refund at 0.72 and not_refund at 0.47 add up to 1.19.
Here is where it bites in practice. You must not move a threshold tuned for Noul over to Choice. For the same judgment, 14% to 17% of the sentences came out with different conclusions.
If the model says yes to whatever you ask, this result is meaningless. That is what I checked first.
| State / question | What I asked | Answer |
|---|---|---|
| Korean / Korean | 이 문장은 영어로 쓰여 있는가? (Is this sentence written in English?) | 0.02 |
| Korean / Korean | 이 문장은 요리법을 설명하는가? (Does this sentence describe a recipe?) | 0.04 |
| Korean / Korean | 이 문장은 한국어로 쓰여 있는가? (Is this sentence written in Korean?) | 0.98 |
| Korean / English | Is this sentence written in English? | 0.01 |
| English / English | Is this sentence about software? | 0.96 |
It reads Korean, it says "no," and it separates 0.02 from 0.98. This is not a global acquiescence bias. That is as far as this rules anything out. The possibility that the wording of the gate question is itself bad remains.
Putting the rules into state
Would it change, then, if I handed it the knowledge the judgment needs? This is the domain adaptation method the TypeSafe documentation recommends: leave the weights alone and ship the reference material inside state.
I took the rules paragraph already written in write-post.md, put it into state alongside the sentence, and ran it again. The input grew from 100 tokens per sentence to 450. The gate set is leakage. That reference material lists the gate words and the exception words by name. So that side is a control for "does it read the reference material at all," and the real test is the held-out set.
| Gate, leaked | Gate + rules | Held-out | Held-out + rules | |
|---|---|---|---|---|
noul accuracy |
0.225 | 0.676 | 0.500 | 0.500 |
| Word-level accuracy | 6/24 | 7/13 | 5/13 | |
| Positives correct | 23/23 | 1/23 | 30/30 | 8/30 |
| Negatives correct | 0/79 | 68/79 | 0/30 | 22/30 |
| 5% budget automation share | 0.010 | 0.314 | 0.000 | 0.050 |
| Median latency | 2,924ms | 6,903ms | 2,908ms | 6,918ms |
The latency is local inference run on an M2 Max, so it is not on the same axis as the Jev API latencies seen earlier. What to look at here is not the absolute value but the 2.4x when the reference material is added.
On the balanced held-out set, sentence-level accuracy went from 0.500 to 0.500, not moving at all. At the word level it actually went down, from 7/13 to 5/13.
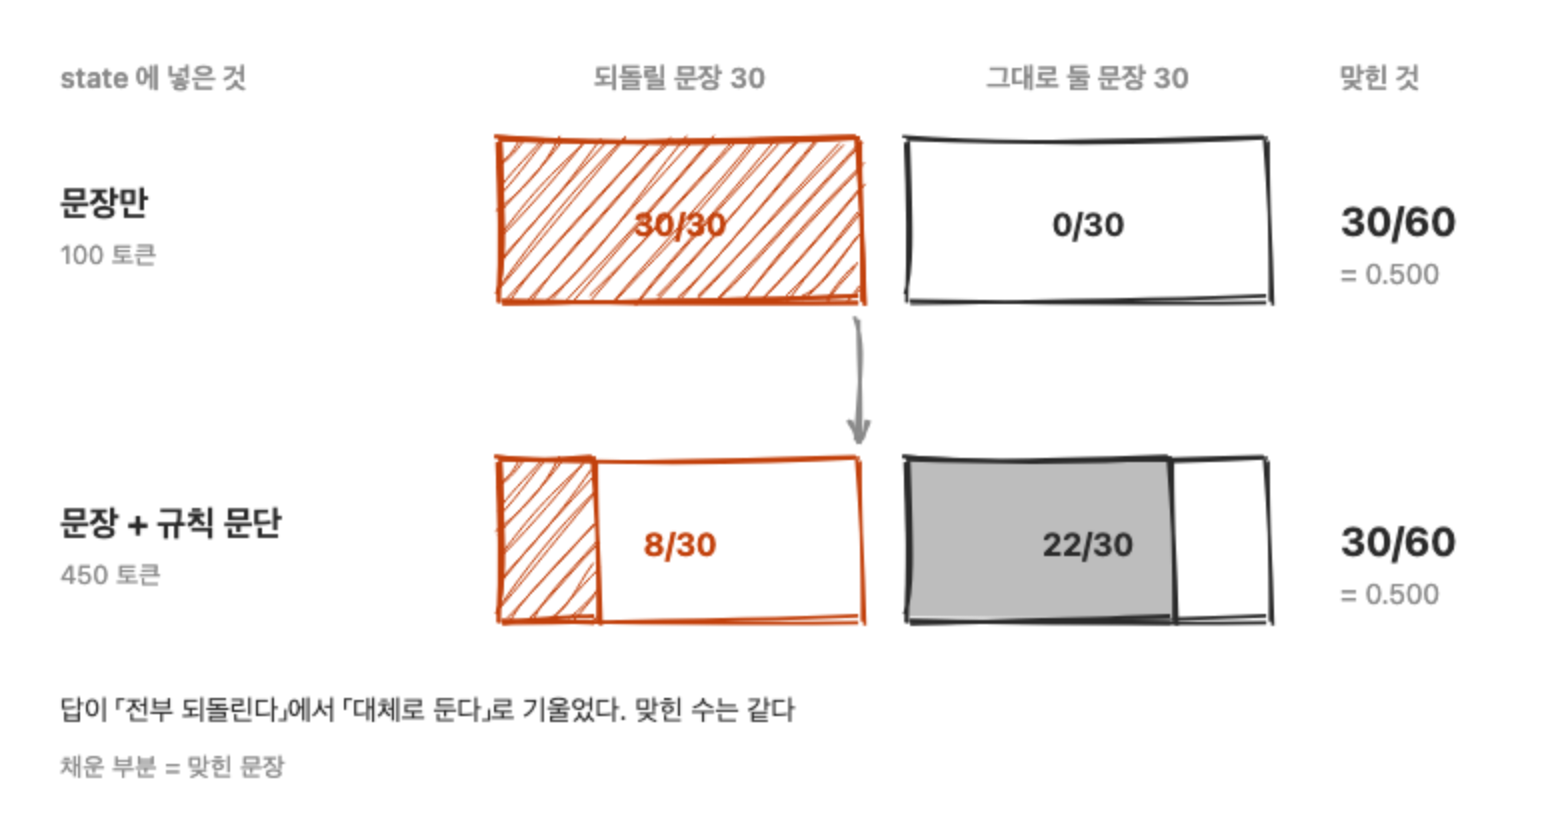
The 0.225 to 0.676 on the gate set is not an improvement in skill. Before, it said "turn it back" on all 102 sentences; once given the reference material it answered that way on only 12. Negatives climbed from 0/79 to 68/79, but positives collapsed from 23/23 to 1/23. That set has more negatives, 79 against 23, so a constant that says "mostly leave it" automatically scores higher. It did not learn the distinction; it changed which way it leans.
That does not mean the model is not reading the sentence. For the same sentences containing the same word, the predictions scattered sentence by sentence once the reference material was given. The standard deviation for 로더 grew from 0.096 to 0.217, and 뮤테이션 from 0.042 to 0.236. It reads, but it cannot distinguish.
And this result also shakes the previous section's reading. If a single piece of state text flips the output wholesale, then the "turn everything back" of the first run may be a shortcoming of the question's wording rather than a limit of the model. This post has not ruled that possibility out.
One thing improved noticeably. The sum of the probabilities for "turn it back" and "leave it" closed from 1.508 to 0.963 on the held-out set, and the sentences deviating far from 1 fell from 59 to 18. Yet the accuracy did not move. Two questions' probabilities agreeing with each other and those probabilities being right are different things.
Where decision models belong
Reading this far, it is easy to lean toward the conclusion that this whole model category is useless, but lining up the published benchmarks says otherwise.
| Task | n | Jev | Comparison |
|---|---|---|---|
| Spam, in distribution | 18,514 | 98.3% | TF-IDF regression 98.4% |
| Spam, out of distribution | 2,876 | 98.6% | TF-IDF regression 73.0% |
| Phishing | 2,000 | 62.6% | Haiku 4.5 81.3%, rule baseline 91.6% |
| Rerank, 8 English sets | 1,617 | nDCG@10 0.692 | Cohere Rerank 4 Pro 0.691 |
Only the rerank row is a search ranking quality metric, so it sits on a different axis from the accuracies in the other rows.
Inside the distribution, a regular expression or a fitted classifier wins or ties. It is the same place where the regular expressions beat the model 1.000 to 0.225 on my gate set. If you can collect labels, training a small model is cheaper, faster, and more accurate. That is something we have been doing for a long time.
The gap opens when the distribution is new and there are no labels. On out-of-distribution spam it is 98.6% against 73.0%. The fitted classifier collapses in front of a shape it has never seen, while this side holds. The place for decision models is judgments you cannot collect data for, label, and train on. It is where every situation is new, so labels cannot be gathered, yet the judgment has to be made within seconds.
This frame also explains why my transliteration judgment failed. What that judgment needs is not general reasoning but the specific domain knowledge of which words have settled in Korean technical writing, and for a 9B reimplementation trained on English decision tasks, that is not out of distribution so much as knowledge it simply does not have. That is why giving it the rules in prose did not work either.
In a TechCrunch article, Armin Ronacher, the CTO of Earendil, which builds the Pi harness, put it this way.
At the end of the day, it delegates the hallucination problem a little bit to the user.
It has not removed hallucination; it has handed the judgment to the developer. The TypeSafe documentation also writes that calibration is a property that holds over a batch of predictions, not a guarantee that an individual answer is right, and under the 0% hallucination bar in the launch post, the Nuance entry reads "Our number is not empirical." The form is guaranteed and the content is not.
The 194 projects on jevable
Since it failed on my data, I looked at where other people are using it. jevable.com is an independent curation by a developer named Nikunj, who reviews Jev projects posted on X and collects them. As of September 23, 2026 it lists 194, and the registration dates cluster between September 16 and 20. 152 of them arrived on September 18 alone, three days after the release.
| Category | Count |
|---|---|
| Games | 39 |
| Developer tools | 34 |
| Productivity | 31 |
| Agents | 19 |
| Experiments | 18 |
| Creative tools | 16 |
| Data & research, Finance, Browser extensions, Robotics, Marketing | 37 |
Regrouping by "what is being asked" rather than by category gives three shapes. Every figure below is what the posters wrote in their own posts.
First, classification and routing. Sorting 1,500 emails, classifying tax documents, classifying 1,891 competitor ads in 19 seconds for $0.12, 14 typed checks on a single PR diff, spotting ads among Android notifications, classifying 26 construction drawings in 2.9 seconds. This is the same shape as the loanword gate at the start of this post. As the table in the previous section said, these are places where labels pile up every day, so given time a small classifier trained on your own labels wins or ties. Jev's advantage is on day one, when there are no labels.
Second, action selection loops. A browser agent that hooked into Browser Use and finished a flight search in 7 seconds for $0.0039, computer use that drives a Mac by voice, a game that forks the VM four ways every time Mario dies and picks the branch that survives, an expression engine that decides ten things per message for a 3D character, including its mouth, eyebrows, and gaze. The action space changes at every step, so you cannot collect labels, and the judgment has to come in under a second. This is the same place where the gap opened up on out-of-distribution spam. I think it is also why Games, at 39, is the largest category. A game is an action selection loop where being wrong can be undone.
Third, UI that shows the probability to the user. Ask Jev, which returns only a verdict instead of an answer; JevForm, a branching form that picks the next question by probability; Upweight, which re-sorts the Hacker News front page with six sliders such as technical depth and drama. Since no threshold is hard-coded and a person reads the probability, these have the lowest calibration requirement of anything this post has taken issue with.
One thing stands out. Of the 194 blurbs, 30 mention cost and 53 mention speed, but only 7 mention accuracy or a baseline. This is a lower bound because the blurbs only carry the start of each post, but the direction is clear. Fast and cheap you can know on day one; whether it is right you can only know by measuring, and the measuring side is rare. One of those 7 is jevcal. It says everyone picks thresholds by feel, and given your data and a target accuracy it returns a threshold and an automation rate. It is the procedure the next section recommends, turned into a tool.
How to draw the line
This post's conclusion is this. Do not read the probabilities a model returns as a spec; measure on your own data and draw the line yourself.
The measuring procedure goes like this. Gather 100 or so labeled items, build a table of the actual hit rate per probability bin, and lower the threshold from the top while watching the error rate above it. Once you have set an error budget, the maximum coverage that keeps that budget is the share you can automate. In my experiment, the fact that the actual hit rate above a peak probability of 0.9 was 0.240 was exposed by 102 sentences.
A scale that is off can usually be fixed. If the overconfidence is spread evenly across all the bins, a single temperature straightens out most of it. Kev did exactly that and brought its ECE down from 0.106 to 0.042. The catch is that fitting that temperature requires labels from that distribution, and labels are precisely what you do not have in production. On top of that, temperature cannot change the ordering of the probabilities, so the automatable share does not rise by the same amount. Which is why ordering matters more than scale, and error budget coverage is a more practical metric than ECE.
Had I hardcoded the 0.9 the documentation uses in its example, this gate would have quietly mis-corrected 38 items. No error is raised, so it is a failure that is hard to notice. The TypeSafe documentation does say, right below that example, to test it on your own data. What ends up hardcoded is usually the number above, not the sentence below.
Even without a key, the measuring part you can do today. Kev is published under Apache-2.0 and runs on a laptop.
I would like you to count how many calls in the service you run ask a big model nothing but yes or no. Before you move those calls to a decision model, I would suggest measuring where the line has to go after the move. I kept that order, and that is why I could decide to leave the gate alone. When I get a Jev key I plan to run the same sets again, and if the conclusion changes then, I will write that down too.
참고 자료
[paper] Lambert et al., Tulu 3: naming RLVR [repo] themsquared/jev-benchmark, judging tool call risk